

·
27 min read
On this page
Confidence shows up everywhere in modern AI systems, in a classifier’s output, in a chatbot’s answer, in a retrieval system’s ranking, in an agent’s decision to act, and in whether a stored memory is still worth trusting. These are all versions of the same underlying question: how sure should the system, or the person relying on it, be that this particular output is correct? But the signals that produce a “confidence score” in each of these contexts are genuinely different, and a raw confidence number should never be read as a probability of correctness unless it’s been calibrated against real outcomes.
This guide starts with the broad concept, works through where confidence scores come from and how they’re calculated, and then narrows into one specific and increasingly important case: confidence in AI agent memory, where Mem0’s own implementation offers a concrete example of the pattern in production.
What Is an AI Confidence Score?
An AI confidence score is a numerical signal representing how certain or reliable an AI system estimates a prediction, answer, retrieved result, stored memory, or decision to be. Scores are typically expressed as a probability between 0 and 1, or sometimes rescaled to a 0–10 or 0–100 range depending on the application.
Confidence isn’t a single, uniform thing measured the same way everywhere. It shows up at several distinct layers of an AI system, and each layer’s confidence is calculated differently and answers a slightly different question:
Prediction confidence: how sure a classifier is about which category an input belongs to
Token confidence: how likely a language model considered a specific generated token
Answer confidence: how sure a system is about a complete generated response
Claim confidence: how sure a system is about one specific factual statement within a longer answer
Retrieval confidence: how sure a system is that a retrieved document or passage is actually useful
Memory confidence: how sure a system is that a stored fact is still true
Agent/action confidence: how sure an agent is that a planned action is the right one to take
Memory confidence, covered in depth later in this guide, is one type of AI confidence score, not a separate concept, and not interchangeable with the others.
How Do AI Confidence Scores Work?
At a basic level, most confidence scores come from one of a small number of underlying signals: how the model’s own output probabilities are distributed, how consistently the model produces the same answer across multiple attempts, how the model itself describes its own certainty in words, or how an external system evaluates the model’s output after the fact.
None of these signals is automatically a probability of correctness. A model can produce a very confident-looking number, high softmax probability, a stated “95% confident,” strong agreement across samples, and still be wrong, because the signal reflects something about the model’s internal state or output distribution, not a verified track record against ground truth. Turning a raw signal into something you can actually trust requires calibration, covered in detail further down this guide.
Types of AI Confidence Scores
Prediction Confidence
Common in traditional machine learning classifiers. An image classifier might output Cat — 92%, Dog — 6%, Fox — 2%. The confidence represents the model’s relative certainty among its predicted classes, derived directly from its output distribution.
Token-Level Confidence
LLMs generate text token by token, and each generated token can have an associated probability or log probability. In the sentence “Paris is the capital of France,” the model may assign a very high probability to the token “Paris” given that context, a signal of local confidence at that specific point in generation.
Answer-Level Confidence
A system attempts to estimate confidence in a complete generated answer, not just one token. This is harder than token-level confidence because a long answer consists of many token probabilities, and there’s no single obvious way to combine them into one meaningful number.
Verbalized Confidence
The LLM is directly asked to estimate its own confidence, for example: “How confident are you that this answer is correct?” with a response like “I am 85% confident.” Yang et al.’s 2024 study on this found it can work reasonably well, but reliability depends heavily on exactly how the model is prompted, not just which model is used. Self-reported confidence should not automatically be interpreted as a calibrated correctness probability.
Self-Consistency / Sampling Confidence
Generate several answers to the same question and check whether they agree. If 9 out of 10 generations say “Paris” and 1 says “Lyon,” that agreement rate can be used as a confidence signal, higher agreement suggesting the model is converging on a stable answer rather than guessing.
Retrieval Confidence
Used in RAG and search systems. Confidence here may depend on similarity score, reranker score, source relevance, the number of supporting documents found, or agreement between multiple retrieved sources.
Memory Confidence
Confidence that a piece of stored information remains valid, trustworthy, and useful, given everything that’s happened since it was written. This is the type covered in full depth later in this guide, and it’s where Mem0’s own implementation becomes directly relevant.
Agent / Action Confidence
AI agents estimate confidence before selecting a tool, choosing an action, executing a plan, using a retrieved memory, making an API call, or returning an answer. This layer of confidence determines not what the agent believes, but what it decides to do about it.
How Are AI Confidence Scores Calculated?
Output Probability and Softmax Scores
For classifiers, confidence commonly comes from the model’s output probability distribution, typically produced by a softmax layer that converts raw model outputs into normalized scores that sum to one. It’s worth being precise here: a softmax score is not automatically a calibrated probability. It’s a normalized number, and whether it actually matches real-world correctness rates has to be checked separately, which is exactly what calibration measures.
Token Log Probabilities
LLMs can expose token-level probabilities, or log probabilities (logprobs), indicating how likely the model considered each generated token at the moment it generated it.
Sequence Probability
Token probabilities can be aggregated to estimate confidence in an entire generated sequence. This gets harder for longer answers, since the combined probability of a long sequence of tokens tends to shrink simply because there are more tokens involved, not necessarily because the model is less sure of the content.
Self-Consistency
Generate a response multiple times and measure how often the outputs agree. Greater consistency across independent generations is treated as one signal of confidence, though correlated sampling (the same biases showing up in every generation) can make this signal less independent than it looks.
Semantic Entropy
An uncertainty-estimation technique that compares whether multiple generated responses express the same underlying meaning, even if worded differently, rather than requiring exact text matches. Two answers that say the same thing in different words should count as agreement; semantic entropy is designed to capture that.
Verbalized Confidence
Asking the model directly to state a confidence number. Useful and simple to implement, since it requires only a prompt change, but it needs calibration and validation before being trusted, for the same reason self-reported confidence generally does: models can sound certain without being accurate.
External Evaluators
A second model or classifier can evaluate the first model’s output for factuality, source support, completeness, or contradictions, and contribute its own score to an overall confidence estimate. This adds a layer of independent judgment the original model’s own output can’t provide on its own.
AI Confidence Score vs. Probability
A confidence score is not automatically the probability that an answer is correct. If an AI system says “Confidence: 90%,” that does not necessarily mean 90 out of 100 similar answers will actually be correct. That interpretation is only appropriate once the system has been properly calibrated and evaluated against real outcomes, otherwise “90% confidence” is just a number the model produced, not a verified statistical guarantee.
This distinction matters because the words “confidence” and “probability” get used almost interchangeably in casual conversation about AI systems, but treating an uncalibrated confidence score as a true probability is exactly the kind of assumption that leads teams to over-trust a number that hasn’t earned that trust yet.
AI Confidence vs. Uncertainty
Confidence and uncertainty are related, but they aren’t always exact mathematical opposites, and it’s worth distinguishing two different sources of uncertainty that get lumped together.
Aleatoric uncertainty is uncertainty caused by ambiguity or noise inherent in the data itself. A genuinely blurry image may be legitimately difficult to classify no matter how good the model is, the uncertainty lives in the input, not in the model’s knowledge.
Epistemic uncertainty is uncertainty caused by limitations in the model’s own knowledge. A model encountering a domain it has rarely or never seen during training is uncertain because it simply doesn’t know enough, a limitation that, in principle, more or better training data could reduce.
The distinction matters practically: aleatoric uncertainty in a query doesn’t necessarily mean the system is broken, it means the question itself is hard. Epistemic uncertainty is more often a signal that the system is being asked to operate outside what it’s actually equipped to handle.
Confidence vs. Relevance vs. Similarity vs. Accuracy
Metric | What It Measures |
|---|---|
Confidence | How certain the system is |
Probability | Estimated likelihood of an outcome |
Similarity | How close two representations are |
Relevance | How useful something is to a query |
Accuracy | How often outputs are correct |
Uncertainty | How unsure the system is |
These get confused constantly because a high score on one doesn’t imply a high score on another. A memory can be highly relevant but low confidence: a user once said “I live in London,” which is highly relevant to a travel recommendation, but if that statement is several years old, it may have low confidence that it’s still true. Relevance answers “does this match what’s being asked?” Confidence answers “should I trust it if it does?” Those are different questions, and a system that only tracks one of them is missing the other half of the decision.
What Is Confidence Calibration?
Calibration measures whether a system’s predicted confidence corresponds to its actual correctness rate. Imagine an AI system produces 100 answers, each with roughly 80% stated confidence. If the system is properly calibrated, roughly 80 of those 100 answers should actually be correct. If only 55 are correct, the model is overconfident, stating more certainty than it has earned. If 95 are correct, the model may be underconfident, stating less certainty than the evidence actually supports.
Modern neural networks are famously bad at this out of the box; they tend toward overconfidence, which is the central finding behind Guo et al.’s “On Calibration of Modern Neural Networks” (2017), the paper that popularized temperature scaling as a cheap, effective fix.
Calibration Methods
Platt scaling fits a logistic model on top of a classifier’s raw output scores to transform them into calibrated probabilities, a technique that predates the deep learning era but still shows up as a calibration baseline.
Temperature scaling, per Guo et al.’s own description in the paper that introduced it, is specifically a single-parameter variant of Platt scaling: instead of fitting a full logistic model, it rescales a model’s logits by one shared temperature value before the softmax step. That simplicity is exactly why it works well in practice, one parameter is easy to fit reliably even on a small held-out calibration set, and Guo et al. found it outperformed more flexible alternatives, including isotonic regression, on most of the architectures they tested.
Isotonic regression is a non-parametric calibration method, useful specifically when the relationship between raw scores and actual correctness isn’t well described by a simple logistic curve, giving it more flexibility than Platt or temperature scaling at the cost of needing more calibration data to work reliably, and, per Guo et al.’s own comparison, it didn’t outperform temperature scaling on the modern architectures they tested.
How Is AI Confidence Evaluated?
Expected Calibration Error (ECE) measures the gap between a system’s predicted confidence and its actually observed accuracy, averaged across confidence buckets. Lower ECE means better-calibrated confidence.
Brier score measures how close predicted probabilities are to actual binary outcomes (correct or incorrect), a single number that rewards both accuracy and honest confidence simultaneously.
Reliability diagrams visualize predicted confidence against observed accuracy directly, typically as a plot where perfect calibration falls on a diagonal line, with overconfidence bowing below it and underconfidence bowing above it. This kind of chart, showing perfect calibration vs. overconfidence vs. underconfidence side by side, is one of the clearest ways to communicate calibration quality visually.
A Worked Example
An LLM answers 100 factual questions. For 20 of those answers, it states approximately 90% confidence. But only 14 of those 20 answers turn out to be correct. Observed accuracy in that confidence bucket: 14 / 20 = 70%. The model predicted roughly 90% confidence but achieved 70% correctness, meaning the model is overconfident in that specific confidence bucket, exactly the kind of gap ECE and reliability diagrams are built to surface.
How to Interpret AI Confidence Scores
A natural question once you have a confidence number is: is 0.7 good? There’s no universal threshold that answers this. The right cutoff depends on the use case, the specific model, your risk tolerance, whether the score has actually been calibrated, the cost of a wrong answer, and the cost of abstaining or escalating instead.
As one application-specific example, not a universal rule: a system might implement high confidence → answer directly, medium confidence → retrieve additional evidence before answering, and low confidence → ask for clarification, verify further, or escalate. A generic range like “0–30 low, 30–70 medium, 70–100 high” only means anything once it’s tied to a specific, calibrated system, treating such a range as universal is a common and avoidable mistake.
Confidence Thresholds in Production
Confidence becomes operationally useful once it’s wired into a decision pipeline rather than just displayed as a number. A typical shape: a user query comes in, the AI generates an answer, the system calculates confidence, and then routes based on the result. High confidence returns the answer directly. Medium confidence triggers retrieval of additional sources or a verification step before answering. Low confidence triggers abstention, a request for clarification, or escalation to a human.
AI Confidence and Hallucination Detection
Confidence scores can help flag potentially unreliable answers, but high confidence does not guarantee factual correctness. A model can produce a confidently stated, entirely incorrect answer, confidence reflects something about the model’s internal state, not an independent check against reality. Because of this, confidence is best combined with retrieval, source verification, factuality checks, external tools, or cross-model evaluation, rather than relied on alone as a hallucination detector.
Confidence Scores in RAG Systems
A RAG pipeline actually contains several distinct confidence layers stacked on top of each other: the retriever produces a retrieval confidence, a reranker produces a relevance score, the LLM produces a generation confidence, and a source-verification step may produce a final answer confidence. One retrieval similarity score should not automatically be treated as the confidence in the final answer, they measure different stages of the pipeline, and a strong score at one stage doesn’t guarantee a strong result at the next.
Confidence Scores in AI Agents
An autonomous agent has to make a running series of decisions: which tool to use, which memory to retrieve, which action to perform, whether the evidence it has is sufficient, whether a task is actually complete, and whether a human needs to step in. Confidence signals can inform each of these decision points separately.
For example, an agent retrieves a memory with relevance 0.94 and confidence 0.42. That memory is a strong topical match for the current query but potentially outdated or unreliable. A well-designed agent can choose to verify that memory before acting on it rather than treating the high relevance score as license to proceed, exactly the kind of judgment call a memory-confidence signal exists to support.
Levels of Confidence
Confidence exists at several distinct levels, each answering a narrower or broader question than the one next to it:
Token-level confidence: confidence in an individual generated token
Sequence-level confidence: confidence in an entire generated sequence
Claim-level confidence: confidence in one individual factual statement
Answer-level confidence: confidence in the complete response
Retrieval-level confidence: confidence that retrieved information is actually useful or relevant
Memory-level confidence: confidence that a piece of stored memory remains valid
Action-level confidence: confidence that an agent’s planned action is the appropriate one
Common Failure Modes
Overconfidence: the model assigns high confidence to incorrect predictions.
Underconfidence: correct predictions receive unnecessarily low confidence.
Out-of-distribution inputs: inputs differ significantly from what the model was trained or evaluated on, and confidence estimates in this regime become unreliable in either direction.
Domain shift: a system calibrated in one environment can become poorly calibrated once deployed in a different one, since calibration reflects the data it was checked against, not a universal property of the model.
Prompt sensitivity: an LLM’s stated confidence can change meaningfully when the same underlying question is phrased differently, even though the correct answer hasn’t changed.
Self-reported confidence bias: models can produce confident-sounding self-evaluations without those evaluations being reliably calibrated to anything.
Correlated samples: generating the same response multiple times doesn’t necessarily provide independent evidence, if the same bias produces the same wrong answer every time, agreement across samples looks like confidence but isn’t.
Poor calibration dataset: calibration is only as good as the dataset used to perform it; calibrating against an unrepresentative sample produces a system that looks calibrated on paper and isn’t in practice.
Limitations of AI Confidence Scores
A confidence score does not automatically measure truth, factual correctness, safety, reliability, source quality, or the absence of hallucinations. It measures one specific thing, a system’s estimate of its own certainty, and that estimate is only as trustworthy as the calibration behind it. Confidence should be treated as one signal in a broader reliability system, not a standalone guarantee of anything beyond itself.
A Production Evaluation Workflow
A practical path to trustworthy confidence scores in production: collect a representative labeled evaluation dataset, generate raw confidence signals (probabilities, logprobs, self-consistency, evaluator scores), compare those confidence values against actual correctness, measure calibration using ECE, Brier score, or reliability diagrams, apply a calibration method like temperature scaling where needed, set decision thresholds for when the system should answer, verify, or abstain, and then keep monitoring calibration over time, since production data distributions shift and a system calibrated once doesn’t necessarily stay calibrated indefinitely.
Use Cases Across the Confidence Spectrum
Classification: fraud detection, image classification, and spam detection all depend on well-calibrated prediction confidence to set sensible decision thresholds.
Information extraction: confidence that an extracted name, date, or entity is actually correct, before it’s used downstream.
RAG: confidence that retrieved evidence genuinely supports the answer being generated from it.
Customer support: low-confidence answers can be automatically routed to a human agent instead of shown to the customer directly.
Coding agents: agents can flag low-confidence code changes for review before executing them.
Autonomous agents: confidence thresholds can gate whether an agent proceeds with a consequential action on its own or pauses for confirmation.
AI memory: agents can prioritize high-confidence memories in retrieval and flag uncertain ones for verification before acting on them, covered in full below.
When Should AI Ask for Human Review?
Human review is worth triggering when confidence falls below a set threshold, when multiple sources disagree with each other, when retrieved evidence is weak or thin, when the action under consideration is high-risk or hard to reverse, when memory confidence specifically is low, or when the system encounters data meaningfully unlike anything it’s handled before.
Memory Confidence: The AI Agent Memory Case
Say a guess an agent made at session three based on a thin signal sits right next to a fact the user confirmed five separate times. Now, if both get retrieved, then both will be treated the same way, and nothing will even crash. But the agent is just as confidently wrong as it’s confidently right, and there’s no way to tell which case you’re in from outside; which is exactly the mechanism behind why grounded memory reduces hallucinations: a model given specific, high-confidence context has its output probabilities sharpen around the right answer, while low-confidence or stale context leaves room for the model to fill gaps with a plausible guess.
A confidence score in AI agent memory is supposed to fix exactly that. Most people mix it up with the machine learning concept where it relates to the model’s prediction, but here, if you get it wrong, then you won’t have a reliable AI system.
Why Does Memory Need Its Own Confidence Score?
A prediction’s confidence is about how sure the model is about a specific answer. While a memory’s confidence is about something that persists. It simply means how sure we are that this stored fact is still true, given everything that’s happened since it was written. A model can be perfectly calibrated on today’s prediction and still have no mechanism for noticing that a fact it stored three weeks ago has since been contradicted twice.
This is a version of memory staleness; confidence and staleness are two lenses on the same underlying problem: a fact that was true when written and nothing marked the moment it stopped being reliable.
This is the gap a well-designed memory system has to close on its own, and it comes down to a pattern worth naming directly: reinforce, revise, supersede. On every new observation that touches an existing memory, there are three honest outcomes:
Confidence up: If the new observation agrees with what’s stored, that’s evidence; confidence should go up, not stay flat.
Confidence down: If it partially conflicts, that’s also evidence, just in the other direction; confidence should go down, and the memory should get flagged for review, not silently coexist at full strength next to something that contradicts it.
Old fact closed: If the new observation clearly replaces the old fact, that’s not a confidence problem anymore; it’s a supersession. The old fact gets marked as no longer current, does not get deleted, and is not left to compete with the new one on equal footing.
If a lesson is learned from watching an agent fail at the same thing once, then it is low confidence. If that same lesson gets repeated three separate times across a project, then it is more trustworthy and gains higher confidence.
A fact confirmed five times and a fact contradicted twice end up looking identical to it, same shape, same weight, same retrieval priority. That’s not a storage bug; it’s a missing dimension.
How to Calculate the Memory Confidence Score
There isn’t a formula that spits out a universal memory-confidence number the way a softmax spits out a class probability. But you can set up a small state machine that you run every time a new observation touches an existing memory:
Reinforce: If a new observation matches what’s already stored, then it raises the confidence score, and nothing about the fact needs to be changed.
Revise: If a new observation doesn’t clearly disapprove the old fact, but doesn’t fully agree with it either, then the confidence score lowers. In this case, we do not delete the memory; we just stop treating the fact as settled until it regains confidence.
Supersede: If a new observation clearly disapproves of an old fact, then we simply replace it with a new one and mark the old one as retired and do not delete it.
A simple starting point that works without much machinery: track two things per memory, a confidence score and an evidence count. Each reinforcement nudges confidence up by a diminishing amount, each partial conflict nudges it down, and a fixed low-confidence floor triggers a review flag instead of letting the number silently decay to irrelevance.
Building It With Mem0
Mem0 doesn’t store a queryable numeric confidence field on a memory the way it stores expiration_date, but it isn’t hands-off about confidence either. It actually has a real, native gate at ingestion time: client.project.update(custom_instructions=”…”) lets you describe confidence requirements in plain language.
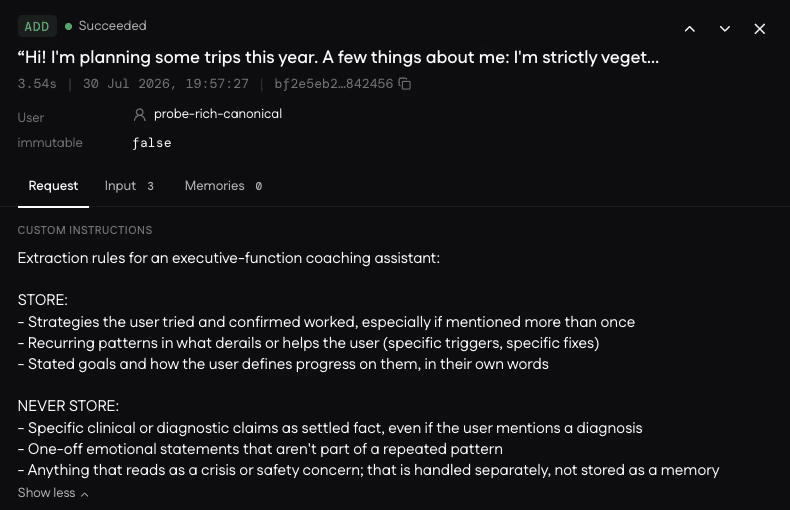
Fig: Mem0 custom instructions
Mem0’s own extraction pipeline will decline to store a fact that doesn’t clear that bar, before it ever becomes a memory.
If this got you interested? Get yourself a Mem0 API Key and let’s dive deeper.
This one’s simple enough to actually run end-to-end, no async timing to fight, and it exercises both layers from this post, not just one.
A few pointers on what’s actually happening there:
The gate runs async. Hosted add() defaults to infer=True, which returns {“status”: “PENDING”, …} immediately, not the stored result. Checking whether the vague statement got filtered means polling get_all(), not reading add()’s return value directly.
The metadata shape is yours, not Mem0’s. confidence, evidence_count, status, these live in the flexible metadata field. Mem0 doesn’t define this schema, its openness is what makes the pattern possible.
Range filtering happens in Python, not the API. search() filters support equality on metadata (status=”confirmed” works), not comparisons like gte. So confidence >= 0.7 gets checked after fetching, which costs nothing since every result already carries its full metadata.
Memory Confidence vs. Relevance, Revisited
One more distinction worth keeping straight: search() also returns a score on every result, but that’s relevance, how well a memory matches your query, not confidence, how sure you should be, it’s still true. A memory can be a perfect relevance match and still be something you shouldn’t fully trust.
Wrapping Up
Confidence isn’t one concept measured one way. A prediction’s confidence, a token’s confidence, a retrieved document’s confidence, and a stored memory’s confidence all answer genuinely different questions, and none of them should be treated as a verified probability of correctness without calibration behind it.
For memory specifically: a confidence score for a single model prediction and a confidence score for a stored memory are answering two different questions, even though they share a name. One asks how sure the model is about this output right now. The other asks how sure the system should be that a fact written days or weeks ago is still true, given everything that’s happened since. Reinforce what agrees, revise what partially conflicts, supersede what’s clearly replaced, and don’t let a five-times-confirmed fact and a one-time guess sit in your memory looking exactly alike.
None of it required reinventing a memory layer to get there. A real ingestion-time gate, a flexible metadata field, an update() that revises cleanly, and a search() that hands back everything you need to make the last judgment call yourself; that’s Mem0 giving you exactly the building blocks this pattern needs, verified end-to-end against a live account rather than assumed.
Frequently Asked Questions
Q. What is an AI confidence score?
A numerical signal representing how certain or reliable an AI system estimates a prediction, answer, retrieved result, stored memory, or decision to be. It shows up at multiple layers (prediction, token, answer, retrieval, memory, agent/action), and these layers aren’t interchangeable.
Q. How is an AI confidence score calculated?
It depends on the layer: classifiers typically use softmax output probabilities, LLMs can expose token log probabilities or be asked to state confidence directly (verbalized confidence), and some systems measure agreement across multiple generated samples (self-consistency) or use a separate external evaluator model.
Q. What does a confidence score of 0.8 mean?
On its own, not much beyond “the system reports being fairly sure.” It only means “80% of similar answers at this confidence level are actually correct” if the system has been calibrated and evaluated against real outcomes to confirm that relationship holds.
Q. Is AI confidence the same as probability?
Not automatically. A confidence score becomes a meaningful probability of correctness only after calibration; an uncalibrated score is just a number the model produced, not a verified statistical guarantee.
Q. What is an LLM confidence score?
A confidence estimate specific to a large language model’s output, derived from token probabilities, verbalized self-assessment, agreement across multiple generations, or an external evaluator, rather than the class-probability approach used by traditional classifiers.
Q. Can ChatGPT or an LLM know how confident it is?
An LLM can be prompted to state a confidence number (verbalized confidence), and this can work reasonably well with the right prompting, but the model isn’t directly introspecting on a true internal probability the way a classifier’s softmax layer does; the reliability of a stated number depends heavily on prompt design and should be validated, not assumed.
Q. How do you measure LLM confidence?
Common approaches include token or sequence log probabilities, verbalized confidence, self-consistency across repeated generations, semantic entropy (checking whether repeated generations agree in meaning, not just exact wording), and external evaluator models.
Q. What is confidence calibration in AI?
The property of a system’s stated confidence actually matching its real-world accuracy. A well-calibrated system that says “80% confident” is correct about 80% of the time at that confidence level; overconfident systems are correct less often than their stated confidence suggests, underconfident systems more often.
Q. What is the difference between confidence and uncertainty?
They’re related but not strict opposites. Uncertainty can come from ambiguity in the input itself (aleatoric) or from gaps in what the model knows (epistemic), and these two sources call for different responses.
Q. What is the difference between confidence and accuracy?
Confidence is what a system says about its own certainty; accuracy is how often it’s actually correct. A system can be highly accurate but poorly calibrated (underconfident), or frequently wrong while sounding very sure (overconfident).
Q. What is a confidence threshold?
A cutoff value used to decide what happens next, answer directly, seek more evidence, or abstain and escalate. There’s no universal threshold; the right value depends on the use case, the cost of errors, and whether the underlying score has been calibrated.
Q. Can confidence scores detect hallucinations?
They can help flag potentially unreliable answers, but high confidence doesn’t guarantee factual correctness, a model can be confidently wrong. Confidence works best combined with retrieval, source verification, and factuality checks, not used alone.
Q. What is retrieval confidence in RAG?
Confidence that a retrieved document or passage is actually useful and relevant to the query, distinct from the LLM’s confidence in the answer it eventually generates using that retrieved content.
Q. What is memory confidence in AI agents?
Confidence that a piece of stored memory remains true, given everything that’s happened since it was written, as opposed to confidence in a single model prediction made right now. See the dedicated section above for how this is calculated and implemented in practice.
Q. Why can an AI be confidently wrong?
Because a confidence score, whatever layer it comes from, reflects the model’s own output distribution or self-assessment rather than an independent check against reality. Without calibration and without combining confidence with verification steps, a system has no built-in mechanism to distinguish a well-supported answer from a plausible-sounding guess.
More on Agent Memory

What Is Memory Staleness in AI? Causes, Risks & Solutions
Understand memory staleness in AI agents, why outdated information leads to errors, and the best techniques to maintain accurate long-term memory.
9 min read
AI Agent Memory: Build vs. Buy
Build when extraction rules, data residency, or low write volume make a vendor hard to justify. Buy when your ship date is weeks out, write volume is high, or compliance is in scope. Both paths retrieve, so token savings don't decide it.
32 min read

Memory for the Trades: Persistent Memory for Field Service AI Agents
Persistent memory gives field service AI agents what the business already knows, past repairs, equipment history, and customer preferences, so the next technician arrives prepared.
13 min read



Aashi Dutt
She is a senior technical content writer at Mem0. She covers agent memory architecture and the engineering decisions behind building agents that actually remember. She experiments with new features and turns research into posts developers can put straight to use.
Start building with memory
Free tier, no card