

·
17 min read

QUICK ANSWER
OpenAI API pricing is usage-based, with standard short-context rates of $10 input/$50 output per million tokens for GPT-6 Astra, $4/$20 for GPT-5.6 Sol, $2/$12 for GPT-5.6 Terra, and $0.20/$1.20 for GPT-5.6 Luna. All prices are in USD. Sol’s promotional rates are available at least through November 21, 2026. Eligible cached inputs and Batch processing offer lower rates, while cache writes, long-context requests, and tools can affect your total bill. Check the model-specific conditions in the official pricing documentation.
OpenAI API Pricing at a Glance
The table below covers nine selected models. All rates are USD per million text tokens, using standard processing and excluding long-context surcharges. Model names link to official pricing documentation.
Model | API ID | Input | Cached input | Cache writes¹ | Output |
|---|---|---|---|---|---|
| $30.00 | No discount | — | $180.00 | |
| $10.00 | $1.00 | $12.50 | $50.00 | |
| $4.00 | $0.40 | $5.00 | $20.00 | |
| $5.00 | $0.50 | — | $30.00 | |
| $2.50 | $0.25 | — | $15.00 | |
| $2.00 | $0.20 | $2.50 | $12.00 | |
| $0.75 | $0.075 | — | $4.50 | |
| $0.20 | $0.02 | $0.25 | $1.20 | |
| $0.20 | $0.02 | — | $1.25 |
Prices verified: October 6, 2026.
¹ Cache writes: “—” means no separate cache-write rate applies; ordinary input processing is still billed. Where a cache-write rate is listed, it replaces—not adds to—the uncached-input rate for those tokens. See OpenAI’s caching rules.
² Promotional pricing: GPT-5.6 Sol’s $4 input/$20 output rates are available at least through November 21, 2026, according to its official model documentation.
³ Deprecation: OpenAI currently marks GPT-5.4 Nano as deprecated. Check availability before using it for a new application.
Long-context conditions: For GPT-6 Astra, GPT-5.6 Sol/Terra/Luna, GPT-5.5, and GPT-5.4, the displayed base rates apply up to 272K input tokens. Higher pricing applies beyond that threshold; consult the linked model documentation for the applicable request/session rules.
Batch, Flex, faster processing modes, tools, storage, and regional processing can change the final bill. This is a selected-model comparison, not the complete OpenAI price list.
What Does GPT-6 Astra Cost?
GPT-6 Astra costs $10 per million input tokens and $50 per million output tokens under standard processing for prompts up to 272K input tokens. Cached input costs $1, while cache writes cost $12.50 per million tokens.
Batch and Flex reduce the applicable standard rates by 50%; Fast mode doubles them. Prompts exceeding 272K input tokens trigger 2× input and cache rates and 1.5× output rates for the entire request, not just the excess tokens. Official Astra pricing
For example, 2,000 uncached input tokens and 1,000 total billable output tokens cost $0.07 under standard processing: $0.02 for input plus $0.05 for output, assuming no cache writes, tools, or other charges. Billable output includes reasoning tokens, not just the visible answer. Reasoning-token billing
How Does OpenAI API Billing Work?
OpenAI API costs depend on the model, processing tier, and usage. Text inference is primarily token-based; other services may charge by media tokens, duration, tool calls, or storage.
Input, Cached Input, and Output Tokens
For cost calculations, distinguish these categories:
Uncached input: Instructions, messages, tool definitions, and context processed at the ordinary input rate.
Cached input: An eligible, matching prompt prefix reused at the model’s cached-input rate.
Cache writes: On applicable models, input written to the cache is charged at the cache-write rate instead of the ordinary input rate, not in addition to it.
Output: Generated text, tool-call arguments, and billable reasoning tokens.
Cache eligibility depends on the model, prefix length, settings, and whether a matching entry remains available. A repeated prompt does not guarantee a cache hit. Use reported usage rather than assuming all repeated text receives a discount. Prompt caching documentation
Reasoning Tokens and Long Context
Reasoning tokens are billed as output tokens, even though they are not shown in the visible answer. Higher reasoning effort can increase usage; do not add reasoning tokens again when they are already included in the reported output total. Reasoning documentation
Long-context pricing thresholds are separate from maximum context limits. For example, Astra applies higher rates to the entire request above its documented threshold, not only the excess tokens. Account for the full input supplied on each call, including conversation history and retrieved information. Astra pricing conditions
Standard, Batch, and Other Processing Options
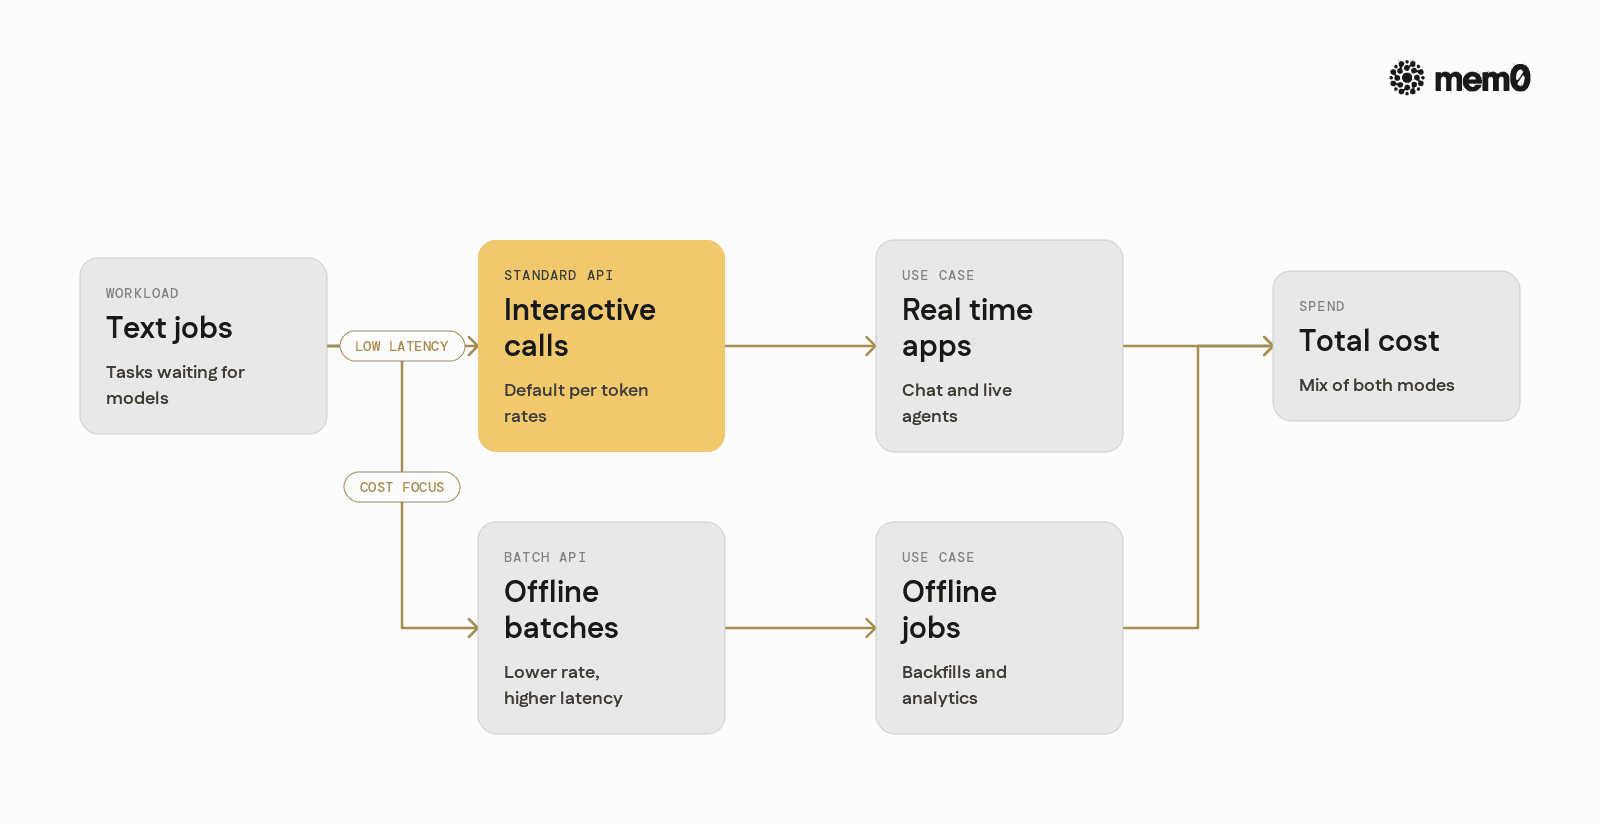
Standard: Regular processing for interactive applications, at the applicable model rates.
Batch: Asynchronous processing for supported workloads, with discounted pricing and a 24-hour completion window. It suits evaluations, classification, and bulk processing. Batch documentation
Other tiers: Supported models may offer Flex or faster processing options with different prices and trade-offs. Check the selected model’s rate card.
Tool, storage, and hosted-execution charges are additional billing categories, not interchangeable processing tiers.
How to Calculate OpenAI API Costs
To calculate OpenAI API costs, multiply each billable token category by its applicable price per million tokens, divide by 1,000,000, and add any separately billed services.
For text inference, the calculation is:
Total token cost = [(uncached input tokens × input rate) + (cached input tokens × cached input rate) + (cache-write input tokens × cache-write rate, where applicable) + (billable output tokens × output rate)] ÷ 1,000,000
Input categories must not overlap. When a cache-write rate applies, it replaces the ordinary input rate for those tokens rather than being added to it. GPT‑5.5 has no additional cache-write charge. OpenAI prompt caching documentation
Billable output includes reasoning tokens where applicable. Do not add a separate reasoning-token surcharge on top of the output total. OpenAI reasoning documentation
The examples below use actual standard-tier model rates checked on October 6, 2026, with illustrative workload assumptions. They exclude Batch discounts, regional pricing uplifts, separately billed tools, infrastructure, and taxes.
Example 1: OpenAI API Cost for 1,000 Requests
Suppose an application uses GPT‑5.4 Mini to answer short customer questions. Each request contains 800 input tokens and generates 400 total billable output tokens, with no cache hits.
GPT‑5.4 Mini’s standard rates are $0.75 per million input tokens and $4.50 per million output tokens. Official GPT‑5.4 Mini pricing
Step 1: Calculate the cost per request.
Input cost: (800 ÷ 1,000,000) × $0.75 = $0.0006.
Output cost: (400 ÷ 1,000,000) × $4.50 = $0.0018.
Total cost per request: $0.0006 + $0.0018 = $0.0024.
Step 2: Scale the calculation to 1,000 requests.
Across 1,000 requests, the application processes 800,000 input tokens and generates 400,000 billable output tokens.
Token category | Total tokens | Rate per 1M tokens | Cost |
|---|---|---|---|
Input | 800,000 | $0.75 | $0.60 |
Output | 400,000 | $4.50 | $1.80 |
Total for 1,000 requests | 1,200,000 | — | $2.40 |
Output accounts for 75% of this example’s token cost, despite representing only one-third of its token volume. Estimating costs from total tokens alone would miss this difference between input and output pricing.
Example 2: Monthly Cost for a Multi-Turn AI Agent
Consider an existing customer-support application handling 10,000 conversations per month. It uses GPT‑5.5 for primary replies and GPT‑5.4 Nano for classification.
For this example, assume:
Main model: Four GPT‑5.5 calls per conversation.
Input per main-model call: An average of 1,300 tokens, including instructions, tool definitions, user messages, supplied history, and retrieved context.
Output per main-model call: 500 total billable tokens.
Classification: Two GPT‑5.4 Nano calls per conversation, each using 200 input tokens and 50 billable output tokens.
Processing: Standard API calls, no cache hits, no retries, and no long-context premium.
GPT‑5.5 costs $5 per million input tokens and $30 per million output tokens. Official GPT‑5.5 pricing
GPT‑5.4 Nano costs $0.20 per million input tokens and $1.25 per million output tokens. It is marked deprecated, so its inclusion illustrates an existing deployment rather than a recommendation for a new application. Official GPT‑5.4 Nano pricing and status
Step 1: Calculate monthly main-model usage.
Four calls across 10,000 conversations produce 40,000 GPT‑5.5 calls:
Input: 40,000 × 1,300 = 52 million tokens.
Output: 40,000 × 500 = 20 million tokens.
Applying the rates:
Input cost: 52 × $5 = $260.
Output cost: 20 × $30 = $600.
Main-model subtotal: $860.
Step 2: Calculate monthly classification usage.
Two classification calls across 10,000 conversations produce 20,000 GPT‑5.4 Nano calls:
Input: 20,000 × 200 = 4 million tokens.
Output: 20,000 × 50 = 1 million tokens.
Applying the rates:
Input cost: 4 × $0.20 = $0.80.
Output cost: 1 × $1.25 = $1.25.
Classification subtotal: $2.05.
Step 3: Combine the model costs.
Model and usage | Monthly tokens | Monthly cost |
|---|---|---|
GPT‑5.5 input | 52 million | $260.00 |
GPT‑5.5 output | 20 million | $600.00 |
GPT‑5.4 Nano input | 4 million | $0.80 |
GPT‑5.4 Nano output | 1 million | $1.25 |
Model inference subtotal | $862.05 |
The estimated inference cost is $862.05 per month, or approximately $0.0862 per conversation.
This is a baseline, not the complete application bill. Add embeddings, vector database usage, separately billed tools, hosting, storage, and applicable taxes when relevant.
Actual costs also depend on conversation length and agent behavior. One additional GPT‑5.5 call per conversation, using the same average token counts, would add $215 per month. Longer histories, retries, and additional tool-processing calls can increase usage, while eligible cache hits can reduce input costs.
For a production estimate, replace these assumed averages with recorded usage across representative conversations. Count every model call and use total billable output—not just the visible answer length.
What Additional OpenAI API Charges Should You Budget For?
Beyond text inference, your application may incur charges for search, storage, code execution, embeddings, and media processing. Budget only for the services your application actually uses.
The following billing details were checked on October 6, 2026.
Service | Billing unit | What to budget for |
|---|---|---|
Embeddings | Input tokens |
|
Web search | Tool calls and search-content tokens | Standard web search costs $10 per 1,000 calls, plus search-content tokens at model rates. Preview variants differ. Tool pricing |
File search | Tool calls and GB-days | $2.50 per 1,000 Responses API calls, plus $0.10 per GB-day of storage after the free 1 GB. Model tokens remain billable. File search pricing |
Hosted Shell and Code Interpreter | Container size and session duration | Published rates start at $0.03 per 20-minute session for a 1 GB container. Eligible sessions use per-minute billing with a five-minute minimum. Container pricing |
Image generation and editing | Model-specific text and image tokens | GPT Image models use token pricing; image settings affect the total. Image pricing |
Transcription and translation | Tokens or audio duration | Billing varies by model. Distinguish actual duration-based rates from estimated per-minute costs. Audio pricing |
Text-to-speech | Model-specific input and output units | Token-priced speech models can charge for both text input and generated audio—not just the text submitted. TTS pricing example |
Conversational Realtime API | Text, audio, and image tokens | Budget for input and output usage. OpenAI currently lists no network-bandwidth or connection charge for these sessions. Realtime billing |
GPT-Live voice sessions | Active session duration plus backend usage | Voice duration is billed per second; backend models and tools are charged separately. This differs from conversational Realtime token billing. GPT-Live billing |
Avoid double-counting Batch and reasoning. Batch is a discounted processing option, not an additional fee layered onto standard inference. Reasoning tokens are billed as output tokens, not through a separate per-step surcharge. Batch documentation, Reasoning documentation
Keep application expenses separate from OpenAI service charges:
Backend hosting, databases, and network infrastructure.
Third-party vector databases, monitoring, and orchestration services.
Applicable taxes.
Also check endpoint-specific pricing adjustments. Regional processing uplifts are OpenAI pricing conditions, not the same thing as local taxes. Regional pricing conditions
A practical budget should therefore track model inference, tools and media, storage and execution, external infrastructure, and taxes as distinct components.
How Does OpenAI API Pricing Compare with Other Major AI APIs?
The table compares selected text-model API rates in October 2026. Prices are in USD per 1 million tokens at standard processing rates; the models are examples, not equivalent performance tiers.
Provider | Model | Input | Output | Cached input |
|---|---|---|---|---|
OpenAI | GPT-5.6 Sol | $4.00 | $20.00 | $0.40 |
OpenAI | GPT-5.6 Luna | $0.20 | $1.20 | $0.02 |
Gemini 3.1 Pro Preview | $2.00 | $12.00 | $0.20 | |
Gemini 3.1 Flash-Lite | $0.25 | $1.50 | $0.025 | |
Anthropic | Claude Opus 5 | $5.00 | $25.00 | $0.50 |
Anthropic | Claude Haiku 4.5 | $1.00 | $5.00 | $0.10 |
xAI | Grok 4.6 | $2.00 | $6.00 | $0.50 |
xAI | Grok 4.3 | $1.25 | $2.50 | $0.20 |
Meta | Muse Spark 1.3 — Standard | $1.25 | $4.25 | $0.15 |
Meta | Muse Spark 1.3 — Contributor | $0.10 | $0.20 | $0.002 |
How to Choose a Cost-Effective OpenAI Model
The model with the lowest per-token price is not always the cheapest option for your workload. A model poorly suited to the task may need more retries, longer outputs, or extra tool calls, increasing overall spend.
Use the following process to compare models:
Define the task and quality bar: Set measurable requirements, such as customer support resolution rate, summary accuracy, or code correctness. Decide what counts as a successful outcome before comparing costs.
Estimate your token mix: Some tasks are input-heavy, such as summarizing long documents. Others are output-heavy, such as generating detailed reports. A model with cheaper input tokens may be more economical for summarization, provided it meets your quality requirements. Include cached input and total billable output, including reasoning tokens, in your estimates.
Consider latency and throughput constraints: Interactive applications need acceptable response times and sufficient request capacity. Offline workloads can use supported Batch processing to trade a longer turnaround time for lower costs. OpenAI cost optimization guidance
Check context requirements: If your application must process long histories or large documents, compare context limits and any applicable long-context pricing. Compare context windows and persistent memory when deciding whether to resend long histories or retrieve selected information. Include retrieval and storage costs, and test whether the approach preserves answer quality.
Measure cost per successful task: Run model candidates on the same representative test cases. Track input, cached input, billable output, tool usage, retries, and fallbacks. Measure how often each configuration meets your quality bar and how long it takes.
Then calculate:
Effective cost per successful outcome = Total cost of all attempts, including retries and fallbacks ÷ Number of outcomes that meet your quality bar.
A model with a higher per-token price can still cost less per successful outcome if it completes the task with fewer retries or tool calls. Validate this through testing, then choose the lowest-cost configuration that meets your quality and latency requirements. OpenAI guidance on cost per successful task
How to Reduce OpenAI API Costs
Reduce OpenAI API costs by routing tasks to suitable models, eliminating unnecessary calls, controlling output length, and using caching or Batch processing where appropriate. Measure savings against task quality, not just a lower token bill.
Route Tasks to Suitable Models

Use smart context construction to remove redundant instructions and supply only the information needed for the current task.
Create a tiered routing strategy: Evaluate a model such as GPT‑5.4 Mini for routine classification, extraction, or straightforward responses. Escalate when validation fails, required information is missing, or testing shows that a task needs a more capable model. Do not rely solely on the model’s self-reported confidence.
Avoid choosing deprecated models as defaults for new deployments. GPT‑5.4 Nano is deprecated, with API removal scheduled for April 1, 2027. OpenAI deprecations
Compare the complete workflow: Test routing strategies on the same representative workload. Include the cost of the initial call, validation, retries, and escalation. A cheaper first call does not save money if most requests subsequently require another model.
Specialize subtasks: Use smaller models for routing or metadata extraction and embeddings for semantic retrieval. Reserve more capable models for synthesis or complex reasoning. A request for a longer explanation alone does not necessarily require a larger model.
For high-stakes tasks, include appropriate validation and human review rather than treating model escalation as a guarantee of correctness.
Reduce Unnecessary Calls and Output
Several application-level controls can reduce wasted usage:
Prevent redundant requests: Debounce duplicate submissions, validate inputs before calling the API, and reuse previously generated answers when they remain accurate and appropriate. Keep answer caches scoped to the correct user, permissions, and data version; similar wording alone does not establish that two requests are equivalent.
Control output length: Ask for the format and detail the task requires, such as three bullet points or a summary. In the Responses API, use
max_output_tokensto cap generation. This limit includes reasoning tokens, so an overly restrictive cap can produce an incomplete answer. Output-token limitsLimit agent loops: Set application-level limits on model calls, tool executions, elapsed time, and total spend per task. Log why workflows reach these limits so you can fix recurring failures.
Handle retries deliberately: Retry recoverable failures with bounded attempts and backoff. Correct malformed inputs or tool responses instead of repeatedly resubmitting them. Reusing a prompt does not make a retry free; account for any billable usage and actual cache hits.
Keep context relevant: Remove redundant instructions and retrieve only the information needed for the current task. If using summaries or external memory, measure their operating costs and verify that removing context does not reduce answer quality.
Use Caching and Batch Processing Where Appropriate
Prompt caching can lower input costs when requests reuse an eligible, unchanged prompt prefix.
Keep stable instructions, tool definitions, and reusable reference material consistent.
Follow the selected model’s eligibility, retention, and cache-control rules.
Measure actual cached-token usage rather than assuming every repeated prompt produces a hit.
Include cache-write charges where applicable when calculating net savings.
Prompt caching reuses input processing; it does not reuse a finished answer or eliminate output-token charges. Prompt caching documentation
Batch processing suits work that does not require an immediate response, such as bulk classification, document summarization, evaluations, or embedding jobs.
OpenAI documents a 50% discount compared with synchronous processing for supported Batch workloads, with a 24-hour completion window. Check model and endpoint eligibility, monitor job results, and retry only failed or unfinished requests to avoid duplicate work. Batch API documentation
Track cost per successful task, completion rate, and latency together. Keep an optimization only when its savings justify any changes in quality or user experience.
Manage Conversation Context with Mem0

Selective memory retrieval is an approach to test against sending the full conversation history with every request. With Mem0, an application can use persistent memory for AI agents to retain useful facts and preferences, retrieve relevant memories, and supply them alongside recent messages and task-specific context.
Persistent memory and prompt caching serve different purposes. Memory helps determine which information to include across conversations. Provider-side prompt caching reuses processing for an eligible, unchanged prompt prefix. The two approaches can work together. OpenAI prompt caching documentation
To evaluate the financial impact, compare the same representative conversations with and without selective memory retrieval. Include:
Model input, cached input, cache writes where applicable, and output costs.
Memory extraction and update processing.
Retrieval, storage, and applicable service fees, without double-counting costs already included in a managed plan.
Account for cache hits in the full-history baseline. A shorter prompt does not necessarily produce a lower bill if it reduces cache reuse or introduces additional memory-processing costs.
Measure answer accuracy, continuity, latency, and cost per successful task together. Test whether important details are omitted or outdated memories affect responses. Adopt the approach when your workload demonstrates a worthwhile improvement; savings are not guaranteed.
Frequently Asked Questions
Does ChatGPT Plus include OpenAI API credits?
No. ChatGPT Plus does not include standard OpenAI API credits. API usage is billed separately from your ChatGPT subscription, so a Plus subscription does not cover requests made by your application using an API key. Subscription and API pricing
Does an OpenAI API key have a separate fee?
No. The key itself is an authentication credential, not a separately priced subscription. You pay for billable model and service usage made through it. Funding your API account is separate from generating a key. API setup
How much do 1,000 OpenAI API requests cost?
There is no fixed per-request price. Using GPT‑5.4 Mini, 1,000 requests with 800 input and 400 billable output tokens each cost $2.40 at standard rates, excluding caching, additional services, pricing uplifts, and taxes. Model rates
Are cached input tokens free?
No. Eligible cache hits use the model’s cached-input rate, usually lower than its ordinary input rate. Cache writes may have different pricing, depending on the model. Repeating a prompt does not guarantee a cache hit. Caching documentation
Is Azure OpenAI pricing the same as direct OpenAI pricing?
Not necessarily. Azure uses its own pricing and billing arrangements, with options varying by model, region, and deployment type. Compare equivalent configurations and distinguish pay-per-token deployments from provisioned capacity before estimating costs. Azure deployment and billing options




Aashi Dutt
She is a senior technical content writer at Mem0. She covers agent memory architecture and the engineering decisions behind building agents that actually remember. She experiments with new features and turns research into posts developers can put straight to use.
Start building with memory
Free tier, no card